
Kapso
A Self-Improving AI Software Factory (for Measurable Objectives)
Learn more · Join Discord · Website

If you like this project, please support us by giving it a star ⭐
News
- IOAI 2026 · the AI Model Track. The International Olympiad in AI is the IMO of the AI era — 471 contestants from 108 countries and territories, six expert-designed tasks under a single-GPU budget. In 2026 it opened IOAI², where AI systems sit the same exam in two fully autonomous 6-hour sessions. Once the clock starts, no human may solve, correct, or improve anything. Kapso entered as one of 14 Founding AI Participants.
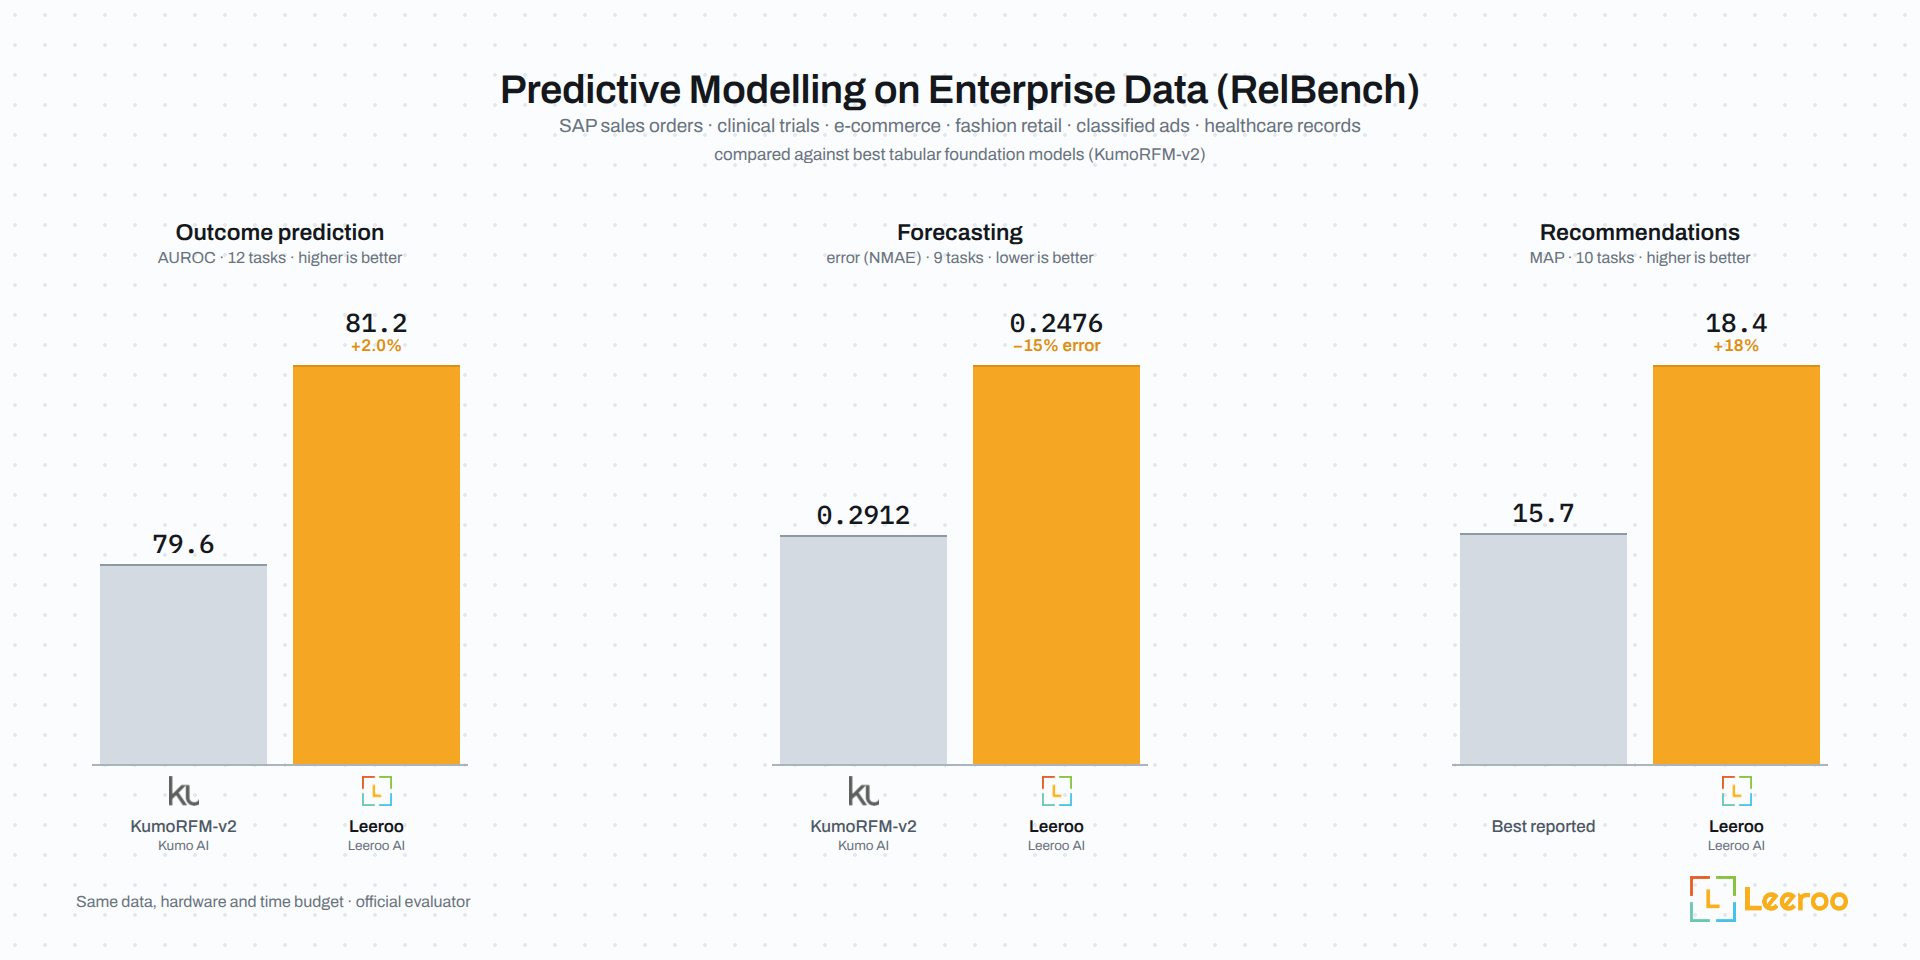
- Beats the best foundation model on RelBench: on Stanford's benchmark for predictive ML over enterprise data, Kapso passes KumoRFM-v2 in outcome prediction (81.2 vs 79.6 AUROC over 12 tasks) and forecasting (0.2476 vs 0.2912 NMAE over 9 tasks, 15% less error), and the best reported results in recommendations (18.4 vs 15.7 MAP over 10 tasks). Published results live on the official RelBench leaderboard.
- Leeroopedia MCP Integration: Kapso now connects to Leeroopedia MCP — your ML & Data Knowledge Wiki. Learnt by AI, built by AI, for AI. A centralized playbook of best practices and expert-level knowledge for Machine Learning and Data domains. Kapso agents use it during ideation and implementation to search knowledge, build plans, diagnose failures, and more.
- Moltbook Agents 🦞: Build AI agents that optimize other agents and debate on Moltbook! Get started →
- Technical Report: Our technical report is now available! Read the paper
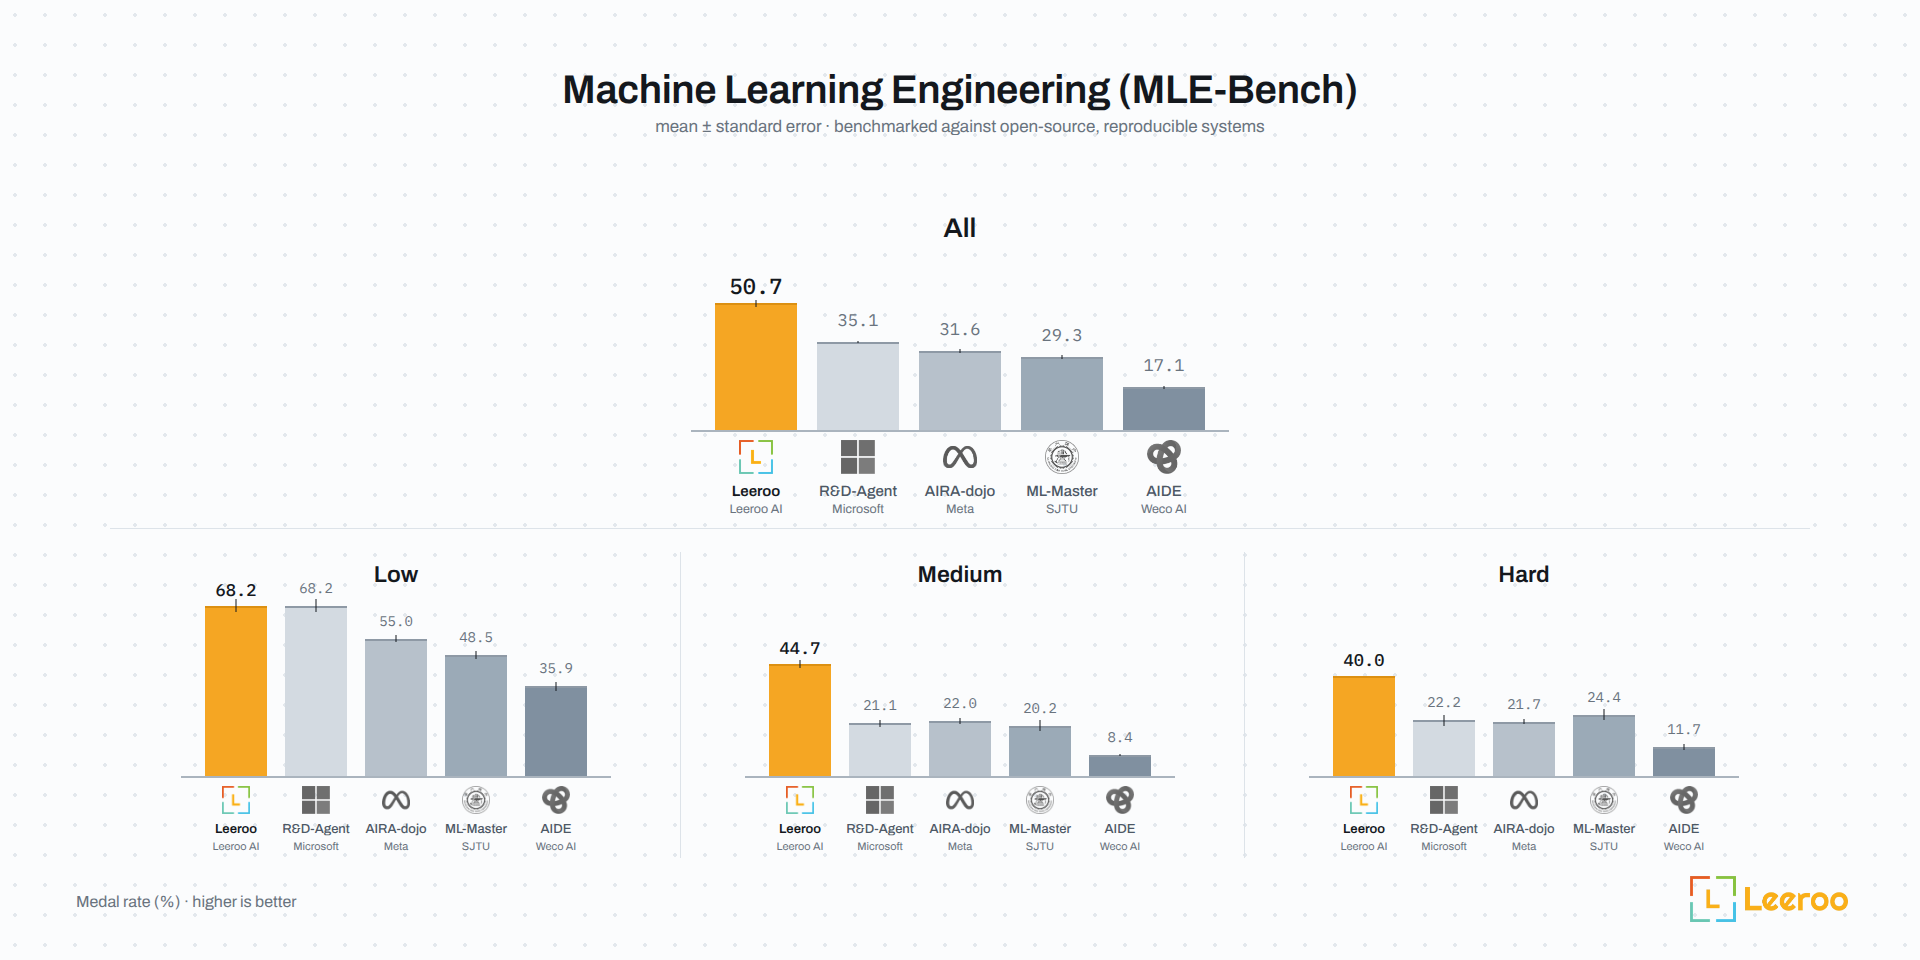
- #1 on MLE-Bench: KAPSO achieved top ranking among open-source systems on Kaggle ML competitions (MLE Benchmark).
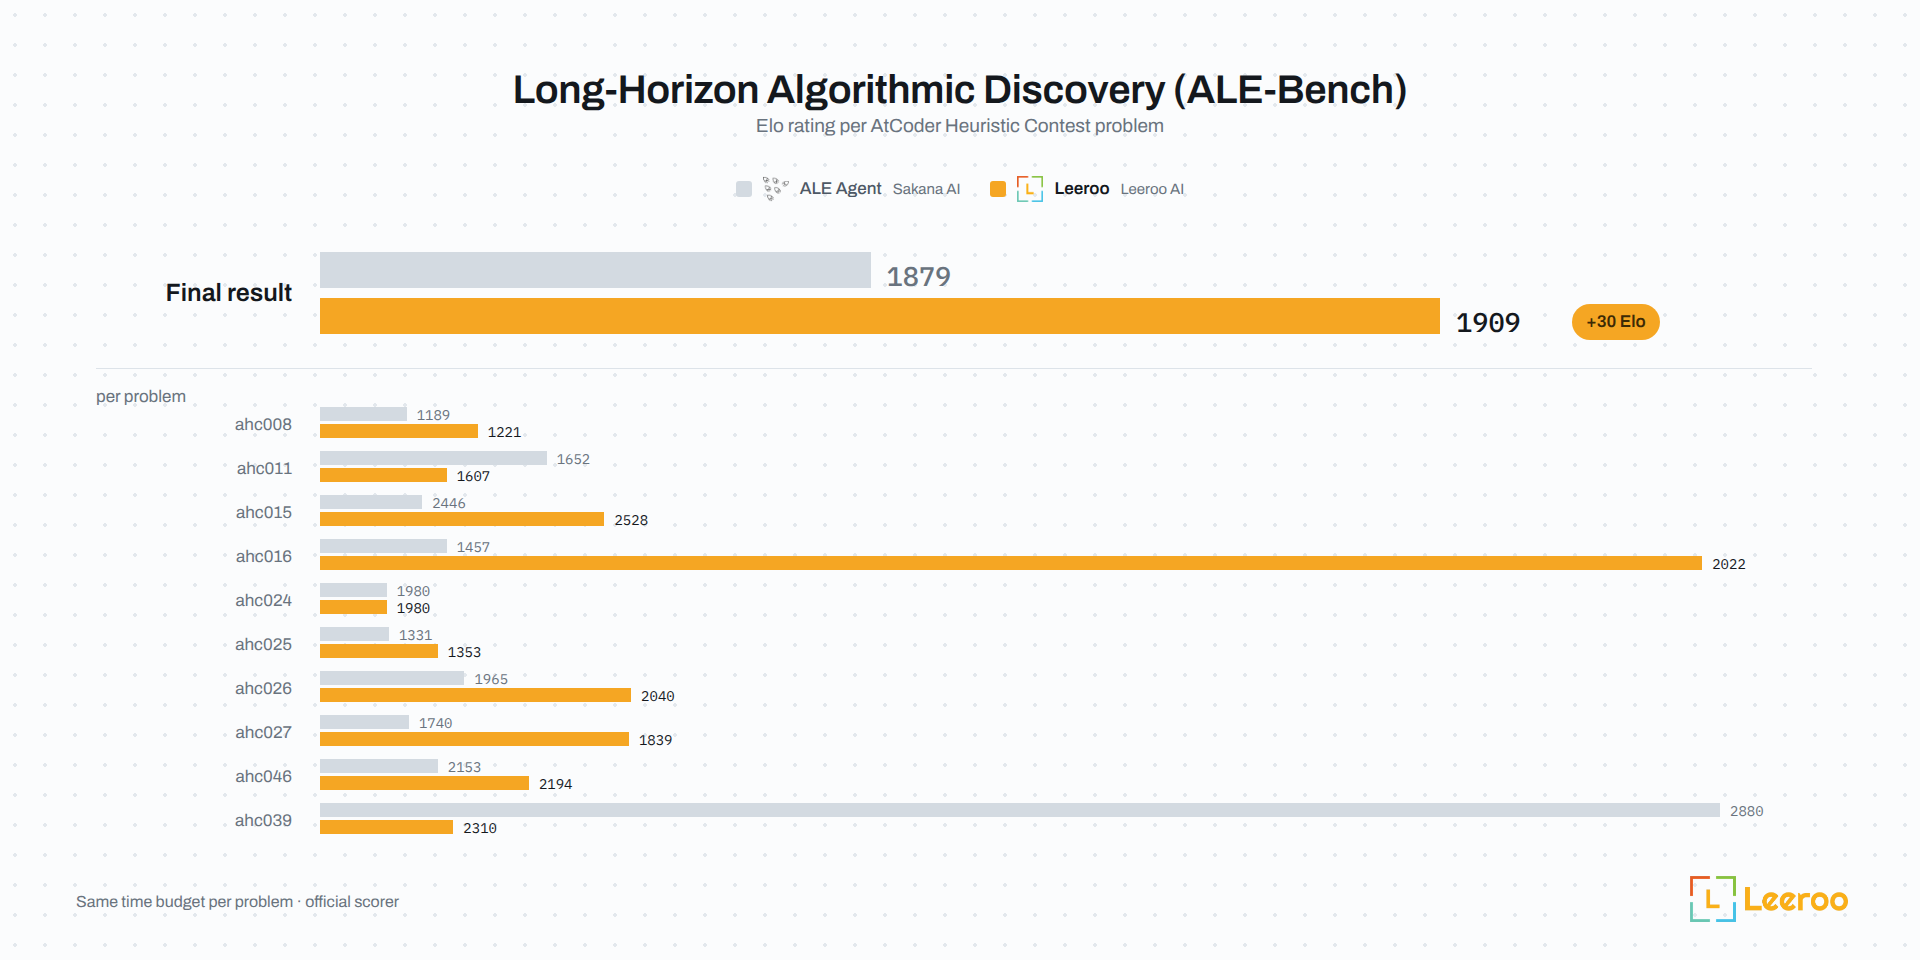
- #1 on ALE-Bench: KAPSO achieved top ranking on long-horizon algorithmic discovery problems (ALE Benchmark).
What is KAPSO?
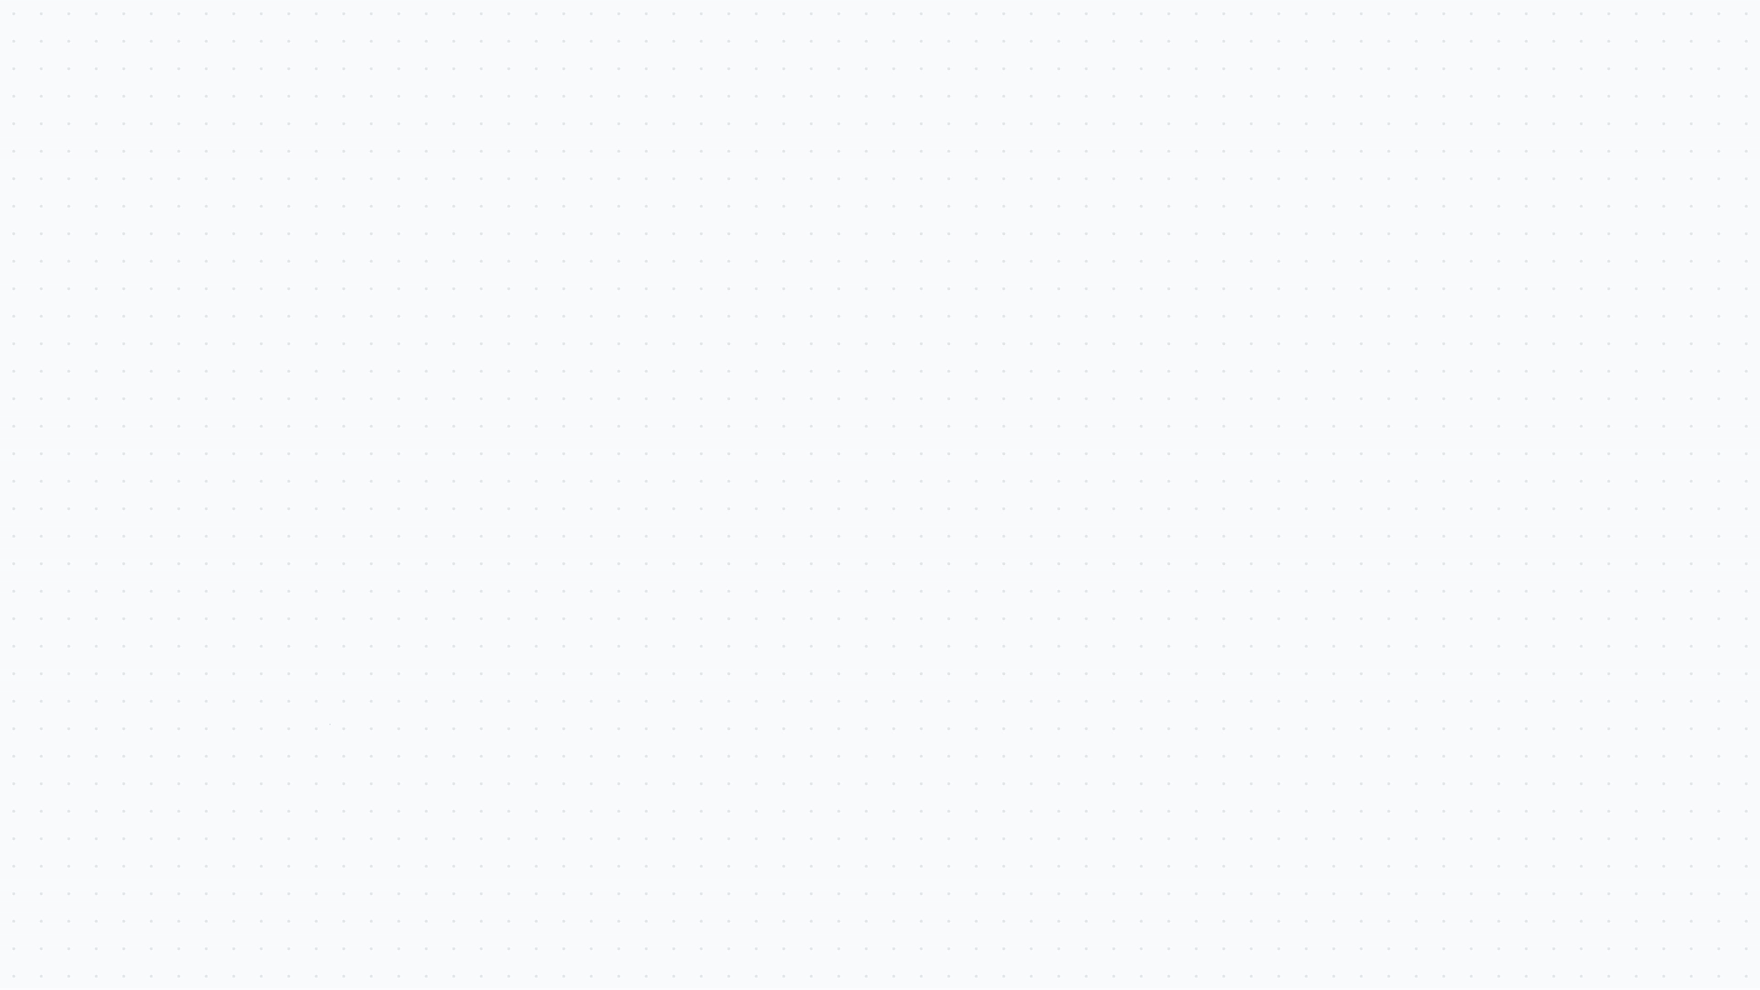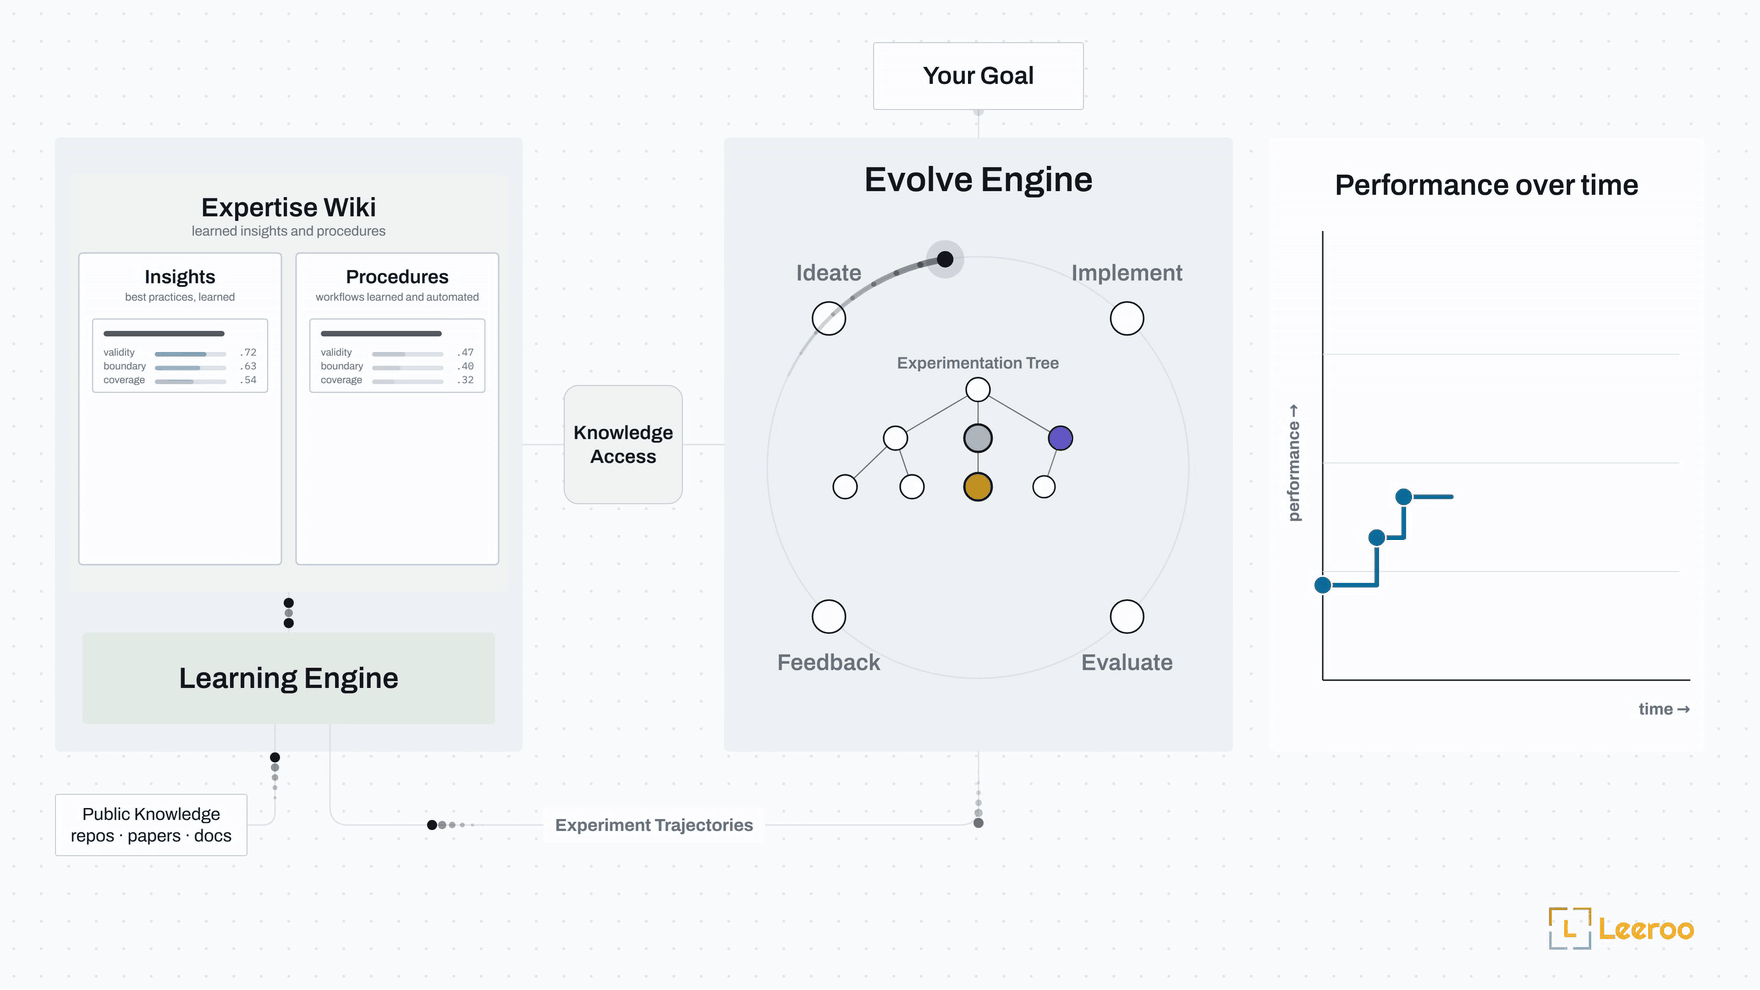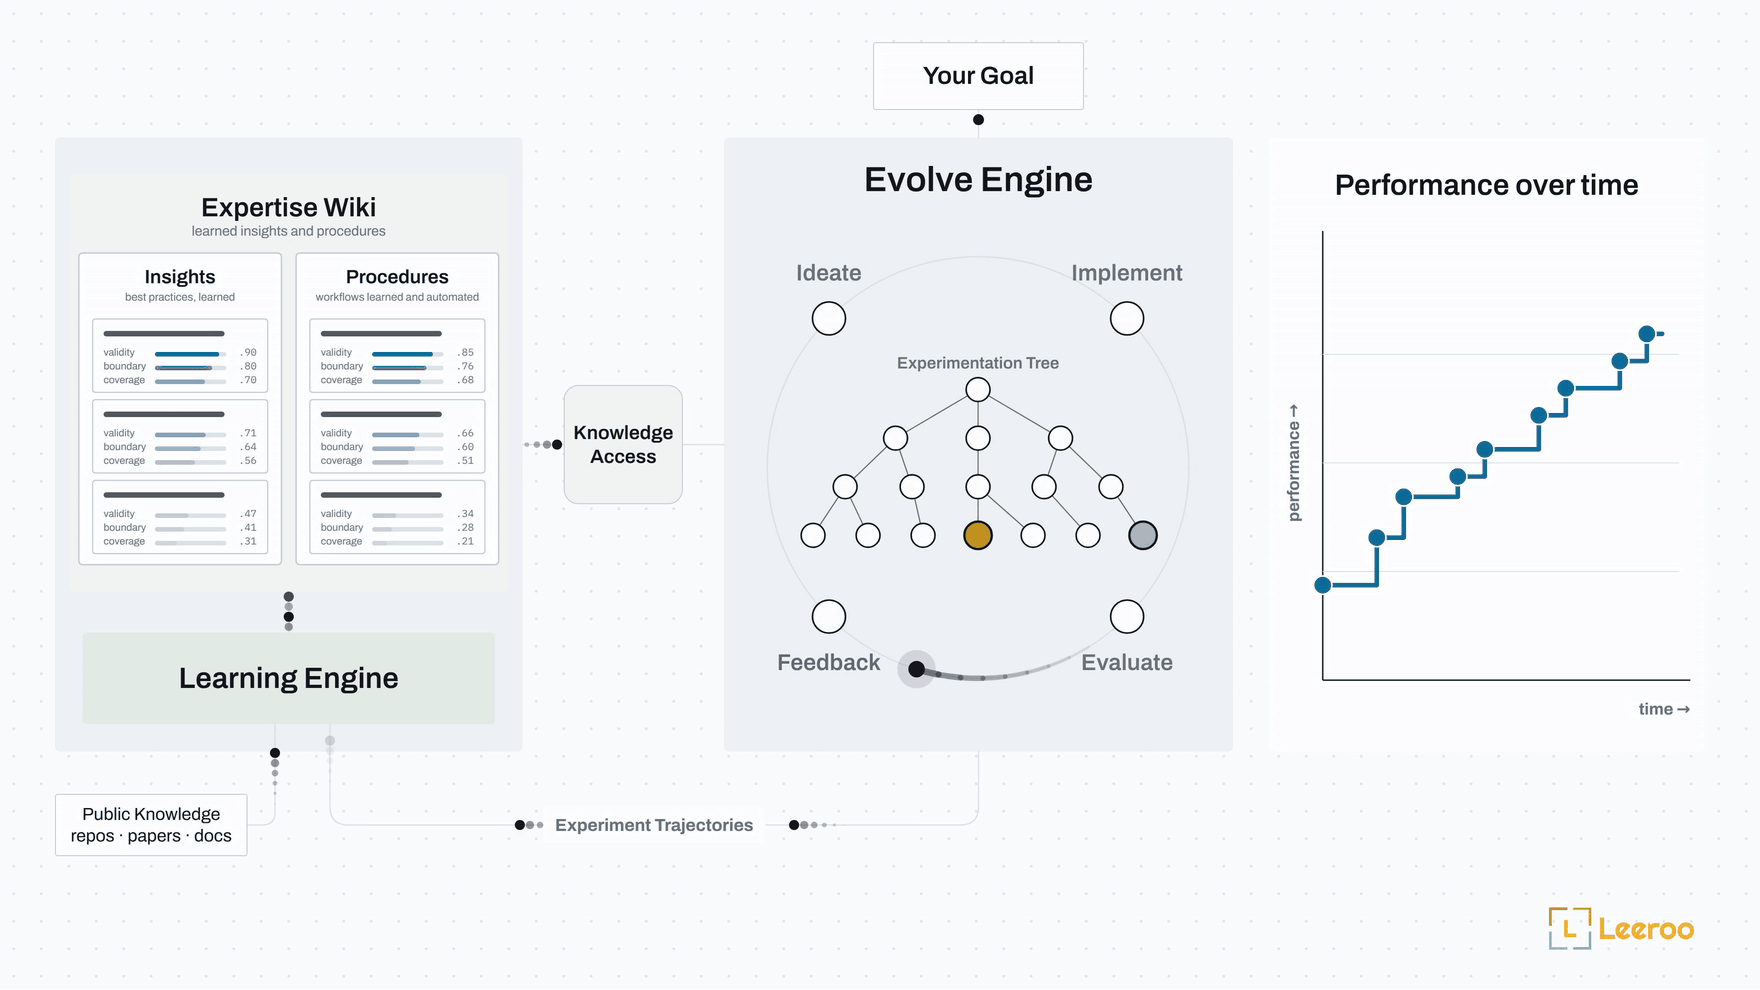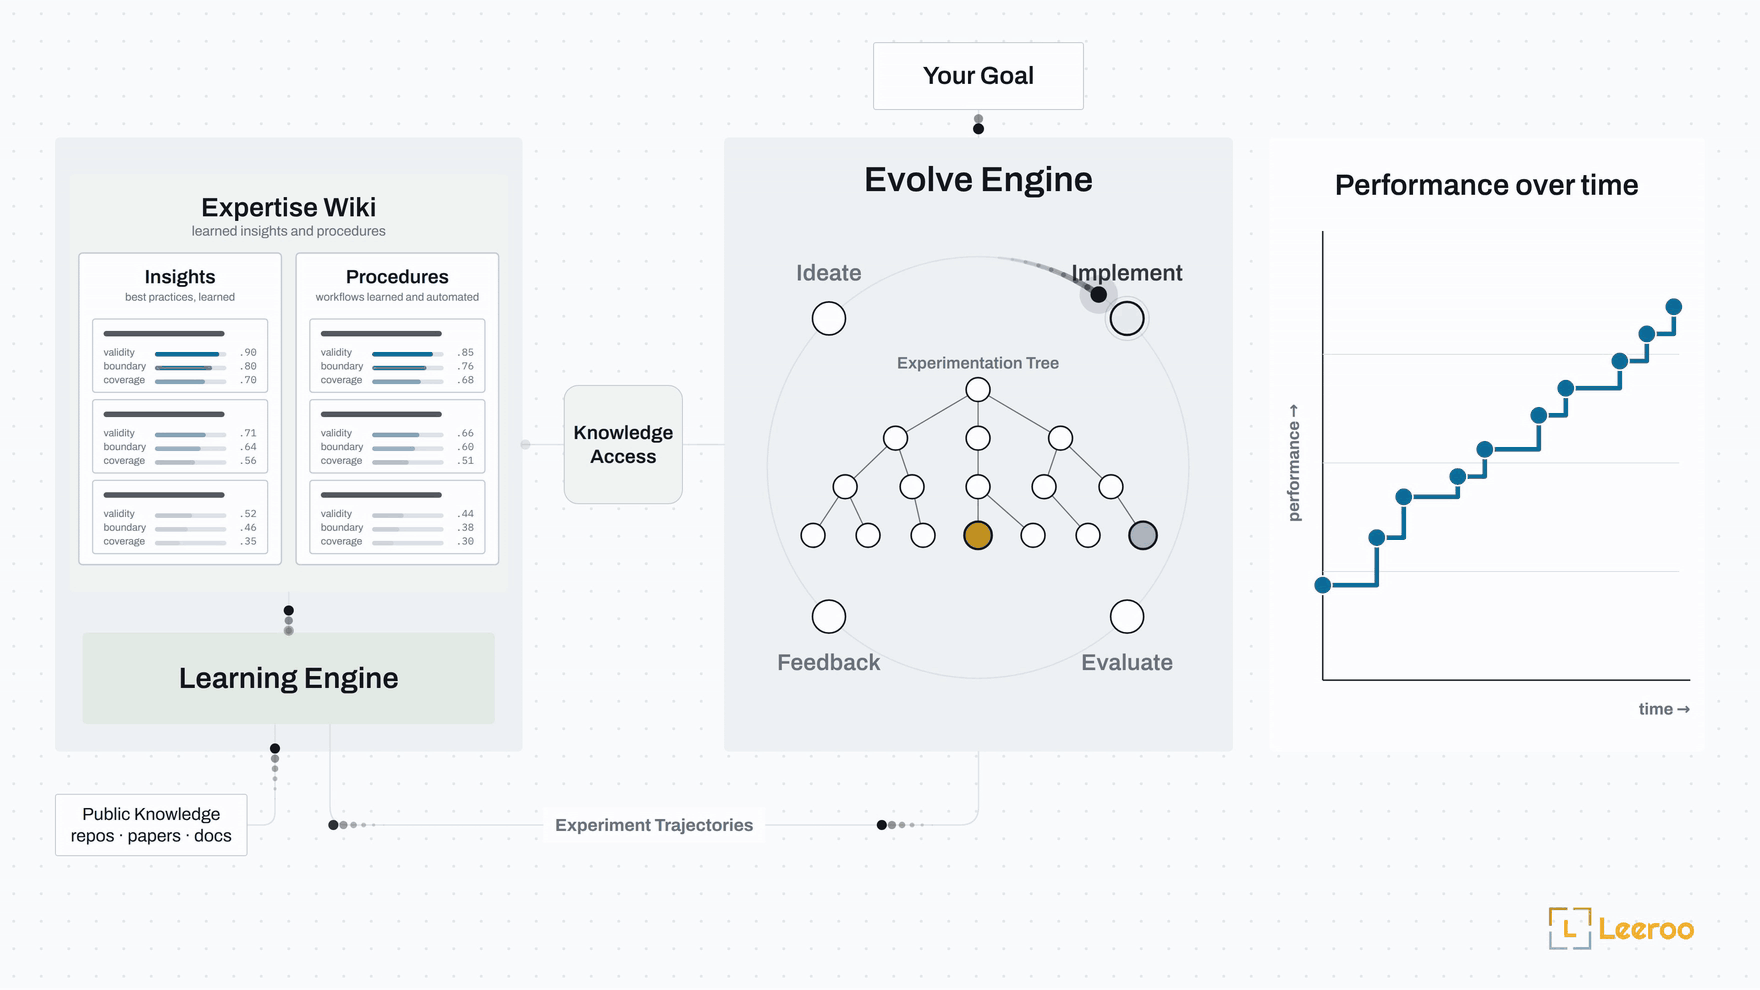
Kapso is a self-improving software factory. State an objective and it runs a campaign: it designs candidate solutions, has coding agents implement them, measures how far each one is from the objective, and keeps refining the closest until the objective is met. The result ships to your infrastructure.
The factory improves with use. When a campaign ends, Kapso studies its own work: which ideas closed the distance to the objective, which did not, and under what conditions. Each finding is kept as a lesson with the evidence that earned it, and a lesson stays trusted only as long as it keeps holding up. Kapso also reads outside your walls, repositories and papers, and folds what it finds into the same knowledge hub. Every new campaign begins from that hub, so it starts with what earlier work already established, about the problem and about your systems.
Kapso is an open-source Python framework by Leeroo, published on PyPI as leeroo-kapso.
The Four Pillars
| Pillar | Method | Description |
|--------|--------|-------------|
| Evolve | .evolve() | Run iterative experiments to build software for a goal. Uses tree search, coding agents, and KG context to generate and refine solutions. |
| Learn | .learn() / .learn_knowledge() | Two memories: learn() mines your own finished campaigns into evidence-priced knowledge cards (experience); learn_knowledge() ingests repositories and research into the Knowledge Graph (imported knowledge). |
| Research | .research() | Run deep web research to gather ideas and implementation references. Returns structured findings you can feed into the knowledge base or use as context for evolving solutions. |
| Deploy | .deploy() | Turn a solution into running software. Supports local execution, Docker containers, or cloud platforms like Modal. |
🚀 Quickstart
Installation
1. Prerequisites. Kapso runs its inference through coding-agent CLIs (there is no direct-API fallback), so you need Node.js and both agent CLIs logged in before anything works:
# Node.js 18+ (https://nodejs.org), then:
npm install -g @openai/codex            # research, judging, utilities
codex login
npm install -g @anthropic-ai/claude-code  # ideation + implementation (default mode)
claude auth login
Add an OpenAI key for embeddings (memory and knowledge-search indexing):
echo 'OPENAI_API_KEY=sk-...' >> .env2. Install the package (Python 3.10+):
pip install leeroo-kapsoThe package is leeroo-kapso. The PyPI package named kapso is an unrelated
WhatsApp tool that installs a kapso command of its own and shadows this one;
if it is present, pip uninstall kapso first.
3. Verify the setup:
kapso doctordoctor reports what your config actually needs, and names the exact
fix for anything missing. Requirements follow the config, so an all-codex
setup is never asked for claude. Narrow it to one verb to see just that
verb's requirements:
kapso doctor evolve # or research / learn_knowledge / learn / deployThose are the same checks the verb itself runs before it does any work —
kapso.evolve(...) fails in seconds on a missing CLI rather than deep
inside a session. Items marked [-- ] are optional; they limit features
you may not need (docker, Weaviate, Neo4j, the deploy targets).
Knowledge-graph backends (optional) — learn_knowledge() and
kg_index store into local Weaviate + Neo4j. From a source checkout:
bash scripts/start_infra.sh # starts both via dockerFrom source (for development)
git clone https://github.com/leeroo-ai/kapso.git
cd kapso
conda create -n kapso python=3.12 && conda activate kapso
pip install -e .
The legacy aider adapter is an extra (pip install "leeroo-kapso[aider]",
Python <3.13); the default claude/codex agents need no extras.
Leeroopedia MCP (optional) — connect Kapso to Leeroopedia, a curated ML/AI knowledge base. Get an API key from the Leeroopedia dashboard, then:
pip install leeroopedia-mcp
echo 'LEEROOPEDIA_API_KEY=kpsk_your_key_here' >> .env
Basic Usage
The core loop needs nothing beyond the prerequisites above:
from kapso import Kapso
kapso = Kapso()   # no knowledge graph needed to start
Evolve: build a solution through experimentation. The campaign prints
status: <path> at launch — watch it live from another terminal with
    kapso watch ./campaign
If a session needs something only you can provide (an API key, a file),
the campaign pauses and kapso inbox reply resumes it:
    https://docs.leeroo.com/docs/evolve/inbox
solution = kapso.evolve(
    goal="Optimize the model in train.py; target accuracy > 0.80 on evaluate.py",
    initial_repo="./my_project",         # or omit to start from scratch
    output_path="./campaign",
    time_budget_minutes=120,
)
print(solution.explain())
Learn from the campaign you just ran: mine the trajectory, grade the
lessons, and bank evidence-priced knowledge cards. The bank (a local
git repo) is created automatically on first use — lessons stay on your
machine until you share them:
    kapso bank connect <git-url>   # or: kapso bank create org/name
after which every learn() pushes the bank there.
lesson = kapso.learn(solution)
print(lesson.explain())
Evolve again — with learning.serving.enabled: true in your config,
the next campaign is served the cards it just earned.
solution2 = kapso.evolve(goal="...", output_path="./campaign2")
With the knowledge-graph backends running, you can also import outside knowledge and serve it to campaigns:
from kapso import Kapso, Source
kapso = Kapso()
Research the web, then ingest findings + a repository into the KG
findings = kapso.research(
    "RLHF and DPO fine-tuning for legal contract analysis",
    mode=["idea", "implementation"],
)
kapso.learn_knowledge(
    Source.Repo("https://github.com/huggingface/trl"),
    findings.ideas,
    findings.implementations,
    wiki_dir="data/wikis",
)
Campaigns on this Kapso now consult the knowledge graph automatically
solution = kapso.evolve(goal="Fine-tune Llama-3.1-8B for clause risk classification")
A note on budgeting: depth="light" bounds the research stage only.
learn_knowledge() extracts everything the material supports — a small
findings set can still become dozens of linked wiki pages and an
hours-long ingest. Ingest time scales with extractable substance, not
with the depth flag; pass fewer sources when you want a faster ingest.
And to turn a solution into running software:
from kapso import DeployStrategy
deployed = kapso.deploy(solution, strategy=DeployStrategy.LOCAL)
result = deployed.run({"input": "data"})
deployed.stop()
Choosing models
Every model Kapso uses is named in one config file. The packaged default
runs evolve sessions on claude-opus-5, the learning crews on
claude-fable-5, and codex roles on gpt-5.6-sol — but model access is
subscription-dependent (a plan can cap one model while serving another).
To run on different models, copy the packaged config, edit, and point
Kapso at yours:
from pathlib import Path
import yaml
from kapso import Kapso
from kapso.kapso import DEFAULT_CONFIG_PATH
config = yaml.safe_load(Path(DEFAULT_CONFIG_PATH).read_text())
e.g. run the learning crews on opus instead of fable:
crews = yaml.safe_dump(config).replace("claude-fable-5", "claude-opus-5")
Path("kapso-config.yaml").write_text(crews)
kapso = Kapso(config_path="kapso-config.yaml")
Text-only inference roles can opt in to openai_compatible Chat Completions.
Set the model and endpoint in your config; credentials stay in the environment.
Load the config with Kapso(config_path=...) or kapso evolve --config ....
Coding and web research still require agents with the corresponding tools.
See the configuration example and limits.
Before a long run, probe every model your config names against your actual subscriptions — a model your login cannot serve fails here in seconds instead of hours into a run. A usage cap on a model you can serve is not visible to a one-token probe:
kapso doctor --models                            # packaged config
kapso doctor --models --config kapso-config.yaml # yours
kapso doctor learn --models                      # just the learning crews
To make that probe part of every call rather than a thing you remember to
run, turn it on in your config. It costs one throwaway token per distinct
{cli, model} pair, which is worth it before an unattended multi-hour
learn():
preflight:
  enabled: true            # static checks before every verb (default)
  live_model_probe: true   # + one-token model probes (default: false)
Model swaps change pacing too: the crew timeout_minutes caps in the
config were calibrated on the default models, and a swapped model that
reasons longer may need them raised.
For detailed integration steps, see the Quickstart and Installation guides.
Examples
| Example | Description | |---------|-------------| | CUDA Optimization | Optimize CUDA kernels for GPU performance | | PyTorch Optimization | Cut wall-clock and memory — fuse ops, kill sync points and host-device chatter, saturate the GPU without changing numerics | | ML Model Development | End-to-end delivery of prediction models — data prep, features, training, and validation evolved into a deployable artifact | | Harness Optimization | Evolve the harness around a model — prompts, decoding, parsing, and scoring tuned against a measurable target | | Agent Optimization | Agents improving agents — workflows, tools, and prompts evolved until the metric climbs |
Supported Benchmarks
| Benchmark | Description | |-----------|-------------| | MLE-Bench | OpenAI's ML-engineering benchmark — full competitions across tabular, vision, text, and audio, from raw data to graded submission | | ALE-Bench | Sakana AI's algorithmic-optimization benchmark — design, implement, and iterate contest heuristics over hours-long searches | | RelBench | Stanford's benchmark for predictive ML over enterprise data — forecasting, classification, and recommendation straight from the multi-table databases of SAP, Amazon, H&M, and more | | IOAI 2026 | Timed olympiad ML across vision, language, and optimization — expert-set tasks, contest hardware, zero human help |
Each benchmark also has a documentation page covering how to run it, its CLI options and what the output holds: IOAI 2026 · MLE-Bench · ALE-Bench · RelBench
📚 Documentation & Support
- Full Documentation: docs.leeroo.com
kapso doctor
- Quickstart — your first campaign
- CLI reference — every command, flag and default
- Python API — every public method on Kapso
- Configuration — every key in config.yaml
- Trajectory learning — the lesson bank, grading and serving
- Evolve — how a campaign runs, and what happens inside one experiment
- Knowledge graph — repositories and papers turned into searchable knowledge
- Deployment — local, Docker, Modal and the other strategies
- Kapso skill for coding agents — launch and resume campaigns from Claude Code, Codex or OpenCode
- From your coding agent: the docs run an MCP server at
https://docs.leeroo.com/mcp, and every page is served as Markdown — see llms.txt and Docs in your coding agent.
claude mcp add --transport http kapso-docs https://docs.leeroo.com/mcp   # Claude Code
codex mcp add kapso-docs --url https://docs.leeroo.com/mcp # Codex CLI- Let your coding agent run Kapso: one
SKILL.mdper agent for Claude Code, Codex and OpenCode lives inskills/— copy the folder for your agent into the project; see Kapso skill for coding agents. - Community: Discord
- Website: leeroo.com
Kapso for Enterprise
Kapso gets better at your company the longer it works: every task feeds a living knowledge bank of your systems, your data, and your hard-won lessons. To onboard Kapso for your challenging enterprise tasks and build that live company context, talk to us.
Contributing
We welcome contributions! Please see our Contributing Guide for details on how to get started.