

English · 简体中文
Local models: NVIDIA CUDA cu124 · AMD ROCm / Windows (experimental) · Apple MPS
Quick start · Website & resources · Installation profiles · Contribute
Amadeus is a real-time multimodal desktop agent that brings voice, character presence, and Agent work into one interface. Speak or type naturally, delegate tasks to specialized Providers, and stay involved through visible progress, permission requests, and controls to resume or take over.
The desktop app and Host run locally, with remote services or local inference selected through model configuration. Character packs are optional: Chat and Work remain available without them.
What Amadeus is trying to solve
Voice assistants, desktop characters, and execution agents usually live in separate windows: one chats, one performs, and another works in a terminal or browser. Once a long task starts, it is difficult to see what is happening, which permission is needed, or whether the work can recover after a failure.
Amadeus connects those experiences into one loop:
- Talk — communicate naturally: speak or type, with interruption across generation, synthesis, and physical playback.
- Embody — make the agent present: voice, subtitles, lip sync, expression, and scene behavior share one playback timeline.
- Act — delegate real work: the main role delegates to registered Work Providers instead of receiving every tool directly.
- Control — stay in charge: Projects, Drafts, Artifacts, progress, permissions, diffs, and results remain visible and recoverable.
[!IMPORTANT]
This repository contains buildable, runnable source. This branch targets
0.15.2 Alpha, not a packaged desktop release.
Amadeus first-party code is open-source under the
GNU Affero General Public License v3.0 (AGPL-3.0).
Third-party code and external assets retain their own terms.
> Want to run it first? See Quick start. For an introduction,
start with What Amadeus is trying to solve.
Demo highlights

Click the image to watch the full 10-minute demo.
| Real-time conversation and performance | Scene-aware working state | |---|---| | !The character speaking in a real-time voice conversation with synchronized subtitles | !The character moves into a working scene and reports the Provider's research result | | Voice, subtitles, lip sync, and expression follow actual playback. | Background work drives character behavior, scene state, and result narration. |
The video demonstrates real-time voice, character performance, desktop scenes, Browser / OpenClaw tasks, and a paper-research flow. The desktop UI, Provider integration, and asset boundaries have continued to evolve, so the video is a product slice rather than a pixel-exact installation preview.
[!NOTE]
The header is a brand illustration; the demo screenshots show the prototype.
Characters, scenes, voices, and other third-party material in the header or
demo are not granted rights by
the Amadeus code license. Public source does not include character packs,
model weights, reference audio, or authoring intermediates without confirmed
redistribution rights.
Current capabilities
| Area | Current public source | |---|---| | Interruptible real-time conversation | Shared microphone lifecycle, independent Wake / Conversation ASR, two-stage endpointing, AEC / barge-in, and interruption across LLM, TTS, and physical playback. | | Remote Main Chat and local voice | DeepSeek V4 Flash Main Chat; Qwen3-ASR / SenseVoice; embedded GPT-SoVITS streaming synthesis (v3 by default, optional experimental v2Pro), continuous playback, and mouth values published before matching PCM windows. | | Character and desktop presentation | SpriteForge graph state, a KTX2/PixiJS runtime, subtitle, lip-sync, and emotion timing; Chat, Work, and headless startup remain available without a character pack. | | Provider Runtime | Pi over native RPC for daily tasks, Codex App Server / Direct Codex for complex coding, Browser for managed pages, and optional OpenClaw. Claude CLI is a committed future direct Provider. | | Durable Work control plane | Projects, default Drafts, WorkItems / Attempts, Continue / Retry, restart recovery, permissions, the Artifact Registry, and structured diffs. | | Artifacts and AUIP | A Work Artifact can be previewed, opened, or attached as a bounded AUIP AppSession so Amadeus can interact with it without turning narration into execution authority. | | Unified settings | Models, Voice, Providers/MCP, vision, character-pack status, and chat appearance are managed in Electron Settings. |
MCP and Skills remain compatible-Provider capabilities even when they share a Host registry; Main Chat cannot invoke MCP tools directly. Remote DeepSeek is the Main Chat baseline; remote ASR/TTS remain explicit compatibility routes. A local voice failure never silently uploads data or creates a second billable request.
Repository map
electron/       Electron main, preload, React renderer, and Settings
server/         authenticated local backend, Host control plane, and AUIP
core/           Main Chat runtime and session integration
agent_host/     Provider contracts, adapters, Work identity, and capabilities
asr/            Conversation / Wake recognition backends
tts/            synthesis backends, sentence pipeline, playback, and mouth signal
render/         SpriteForge runtime adapter and PixiJS renderer
wallpaper/      Electron/Lively hosts and Win32 desktop placement
vn_player/      experimental VN Player integration
assets/         Git-owned UI assets and external runtime-asset destinations
release/        public-source selection, provenance, and deterministic archive policy
main.py is not an application entry; it prints a retirement notice. The
Python entry is uv run --locked --no-sync python -m server.app --port 17777,
and the desktop entry is run_electron_utf8.bat on Windows or
npm run electron:dev from electron/ on macOS. Both discover .venv
automatically; choose an installation profile supported on your platform.
Architecture

The dashed Memory & Persona Runtime is a roadmap extension. Its two-way connection to Main Chat represents proposed context retrieval and updates; storage, memory formation, persona updates, and lifecycle mechanisms remain to be designed.
Three separations are deliberate:
- Main Chat, Work Providers, and AUIP applications are distinct authority domains.
- A shared MCP/Skill registry does not expose those capabilities directly to Main Chat.
- Artifacts, identity, permission, and receipts are Host-verified facts; model narration cannot replace them.
AUIP application sessions
AUIP is Amadeus's cooperative application protocol. It is not a Provider, MCP, or Main Chat tool system. It addresses a different problem: once Work has created a runnable Artifact, how can Amadeus continue collaborating with that application while preserving Host authority?
verified Work Artifact
  -> Host prepares a short-lived attach ticket
  -> application registers declared state/events/actions
  -> bounded AppSession
-> character receives scoped projection and action receipts- The ticket binds the current Session, an immutable Artifact reference, and a TTL. The application submits an Artifact id, not an arbitrary path.
- The Host validates workspace ownership, type, digest, and launch entry, and owns AppSession identity, revision, and action authority.
- The application may publish only declared state and semantic events and receive only declared, authorized typed actions.
- AUIP grants no
work.,provider.,tts.*, arbitrary filesystem, or other-Session authority. - Disconnects become visible state and invalidate pending actions instead of continuing against stale application state.
amadeus.auip/v0. The protocol implementation,
Web SDK, Managed Core, application examples,
and integration tests live in this repository. See
AUIP application sessions.
Code-Amadeus/AUIP documents the current
protocol, public implementation entry points, and future SDK release criteria;
a separately versioned SDK and standalone conformance suite are not yet published.
Quick start
Dependencies are grouped into four capability tiers. Start with the minimal L1
installation, then add the tiers you need. Torch enters at L3/L4 in the default
ladder; optional RAG also adds local embedding/Torch dependencies. Windows is
the reference platform. macOS with Apple Silicon MPS and Linux source deployment
have also been verified on real hardware; macOS L1/L2 has separate installation CI. L3 offers CPU VAD with no NVIDIA GPU requirement. The current L4
cu124 profile targets Windows + NVIDIA. Windows ROCm 7.2.1 has a mutually exclusive
local-rocm experimental lock and validation tools for GPUs in AMD's official
support matrix. Apple Silicon MPS uses the verified
local-mps profile; NVIDIA cu128 remains an experimental Torch 2.7.0 profile.
All profiles use uv and Python 3.12; CI pins uv 0.12.8.
Linux users should start with Linux below.
| Tier | Capability | Platform | Installation |
|---|---|---|---|
| L1 core | Text Chat, Work, Providers, and character rendering | Windows / macOS | uv sync --locked |
| L2 voice | Remote TTS, playback, lip-sync, microphone, and remote ASR | Windows / macOS | uv sync --locked --extra voice |
| L3 CPU VAD | Real-time interruption while the character is speaking | CPU; no NVIDIA GPU required | uv sync --locked --extra voice --extra vad --extra torch-cpu |
| L4 local-cu124 | Local GPT-SoVITS, Qwen3 ASR, and wake word | Windows + NVIDIA GPU | uv sync --locked --extra voice --extra vad --extra local-cu124 |
| Experimental local-rocm | Local GPT-SoVITS / Qwen3 ASR sidecars | Windows + GPU in AMD's official support matrix | uv sync --locked --extra voice --extra vad --extra local-rocm |
The four default tiers and the ROCm experiment use the same .venv. Give the
complete target configuration each time: uv sync is exact and removes packages
from omitted tiers. torch-cpu, local-cu124, local-cu128, local-mps, and local-rocm are pairwise
incompatible. To switch builds, replace the build extra while keeping voice
and vad. See installation profiles and migration.
- Main Chat defaults to remote DeepSeek. llama.cpp is an optional local LLM
- L2 without VAD uses energy-based endpoint detection. Adding VAD enables
- On Windows, check each tier with
uv run --locked --no-sync python tools/verify_python_environment.py --profile
(ci shares the core import checks). For L4, use --profile cu124 --require-cuda-device.
For ROCm, use --profile rocm, then run the GPU compute probe. Import/build
checks do not replace real model and audio-device tests.
- L1 is sufficient for text-only/headless use. Start the backend with
uv run --locked --no-sync python -m server.app --port 17777.
Set TTS_BACKEND=disabled and disable Wake for a strict text-only profile.
Reference hardware
L1/L2 (Windows / macOS)
- CPython 3.12, managed by uv; no system Python installation required
- Node.js 22 (
22.21.1is the current reference) - No GPU required
- CUDA 12.4-compatible NVIDIA GPU, targeting 8 GiB VRAM
- 16 GiB system RAM minimum; 32 GiB recommended
Base environment (L1/L2, Windows / macOS)
Install uv with winget install astral-sh.uv on Windows or brew install uv on
macOS. For L2 on macOS, install PortAudio first with brew install portaudio;
PyAudio builds from source there. Then clone and choose a tier with the same
commands on both platforms:
git clone https://github.com/Code-Amadeus/Amadeus.git
cd Amadeus
uv venv .venv --python 3.12
uv sync --locked                              # L1 core
uv sync --locked --extra voice                # L2 voice (optional)
Keep the environment named .venv. Electron discovers its interpreter
automatically (Scripts/python.exe on Windows, bin/python3 on macOS), without
requiring an AMADEUS_PYTHON override.
Build the Electron frontend on either platform:
cd electron
npm ci
npm run build
cd ..
npm ci uses the project postinstall hook to install Electron and the pinned
Pi runtime for the default daily-task agent. No separate Pi installation is
needed for desktop use. The default Pi connection reuses the same
DEEPSEEK_API_KEY configured for Main Chat under Settings -> Models or in
.env; it does not require another agent installation or login. After restart,
the backend checks the pinned runtime and selected model credentials before Pi
is advertised as available. See Pi configuration for
headless installation, native authentication, and custom model endpoints.
Where network access requires it, configure npm/Electron mirrors, such as
ELECTRON_MIRROR=https://npmmirror.com/mirrors/electron/.
Linux
Linux source deployment has been verified on real hardware. Phase 1 Linux CI (#63) has passed locked L1 + dev installation, environment imports and model-less dependency checks, basic contract tests, Ruff, architecture-view checks, and the Electron build on Ubuntu 24.04. A separate Voice source-build job checks locked installation, AEC import, bundled Abseil selection and related contracts. CI does not cover the Electron GUI, real audio devices, VAD/local model inference, Wayland sessions, or wallpaper integration. Additional jobs check cu128 candidate installation, dependencies and transitions back to CPU VAD; they do not qualify real GPU model inference.
The community has reported desktop and character-rendering results on Arch Linux / Wayland. These reports do not establish compatibility across all distributions or desktop environments. See Linux tracking issue #64 for environment records, known issues, and follow-up work.
Install Git, uv (0.12.8 in CI), and Node.js 22
(22.21.1 in CI), then start with L1, which needs no GPU or voice packages:
git clone https://github.com/Code-Amadeus/Amadeus.git
cd Amadeus
uv venv .venv --python 3.12.10
uv sync --locked
cp .env.example .env
Edit .env, provide DEEPSEEK_API_KEY, set TTS_BACKEND=disabled, and keep
WAKE_ENABLED=false to try the text-only path first. Verify the environment from
the project root:
uv run --locked --no-sync python tools/verify_python_environment.py --profile cpuBuild and launch Electron from a Linux graphical desktop session. The launcher
automatically discovers .venv/bin/python3 and starts the backend:
cd electron
npm ci
npm run build
npm run electron:dev
The desktop npm ci also installs Pi. The default Pi connection reuses the
DeepSeek credential from the base configuration and is checked when the backend
starts; custom model authentication is described in Pi configuration.
For a headless backend instead, run this from the project root:
uv run --locked --no-sync python -m server.app --port 17777For remote voice, recording and playback, install L2 in the same .venv.
On Ubuntu 24.04, install the native prerequisites used by CI first; other Linux
distributions need their corresponding package names:
sudo apt-get update
sudo apt-get install --no-install-recommends -y build-essential pkg-config portaudio19-dev
uv sync --locked --extra voice
uv run --locked --no-sync python tools/verify_python_environment.py --profile voice
For voice, local models, and desktop integration, see the component-specific notes:
- Voice / AEC: Linux uses vendored source based on the official
aec-audio-processing==1.0.1 sdist and forces bundled Abseil 20240722.0 to avoid
selecting an incompatible modern system Abseil. The system installation is
unchanged; Windows/macOS retain their registry artifacts. Source identity,
the isolated patch and removal conditions are in AEC provenance.
Build/import success does not qualify real-device echo cancellation or full voice interaction.
- VAD / NVIDIA: Linux CPU VAD and the
local-cu128candidate have explicit
- Desktop / wallpaper: GUI and Wayland compositor integration need separate
VAD and local models
Use the same .venv as L1/L2 and select the complete capability/build combination.
L3 CPU VAD — real-time interruption: Torch enters as a CPU build.
uv sync --locked --extra voice --extra vad --extra torch-cpu
uv run --locked --no-sync python tools\verify_python_environment.py --profile vad-cpu
L4 local-cu124 — local voice models: select the CUDA profile in that same
environment. On Windows, [tool.uv.sources] routes this extra's Torch/Torchaudio
packages to the PyTorch cu124 index.
uv sync --locked --extra voice --extra vad --extra local-cu124
uv run --locked --no-sync python tools\verify_python_environment.py --profile cu124 --require-cuda-device
The L4 profile pins torch==2.6.0+cu124, torchaudio==2.6.0+cu124, and the local
model dependencies. This is the current qualified local-model profile.
Experimental local-rocm (Windows): this profile targets GPUs in AMD's official
ROCm 7.2.1 Windows PyTorch support matrix. The same .venv can select ROCm 7.2.1,
Torch/Torchaudio 2.9.1, and the local-model dependencies. Persistent Qwen ASR and
GPT-SoVITS sidecars use that environment's interpreter by default. This profile
conflicts with cu124/CPU Torch builds. After installation, run the environment
check and GPU compute validation before loading models. See the
Windows ROCm sidecar guide for supported hardware,
installation commands, and validation steps.
Torch 2.7 profiles: local-cu128 (Windows/Linux x86_64)
and local-mps (Apple Silicon) select locked Torch/Torchaudio 2.7.0 packages.
Apple Silicon MPS has been verified on real hardware; cu128 remains an experimental
NVIDIA profile. Windows cu124 remains the reference, and Windows ROCm retains
AMD's 2.9.1 pair.
# Windows/Linux NVIDIA candidate, including the model dependency set
uv sync --locked --extra voice --extra vad --extra local-cu128
uv run --locked --no-sync python tools/verify_python_environment.py --profile cu128
Apple Silicon MPS
uv sync --locked --extra voice --extra vad --extra local-mps
uv run --locked --no-sync python tools/verify_python_environment.py --profile mps
Select only the command for your platform. Installation and CPU contract CI do
not qualify GPU inference, microphones, continuous playback or interruption.
Issue #67 reports standalone Qwen-ASR MPS results on an M4 Max; the application
currently accepts only CPU/CUDA Qwen device selection. Installing local-mps
does not enable application ASR MPS routing. GPT-SoVITS supports the MPS path
through the local-mps environment.
RTX 50-series users should evaluate cu128; cu124 is not a Blackwell baseline. FlashAttention remains optional. Matching cp312/Torch 2.7/cu128 community Windows and upstream Linux wheels have been located; see Torch 2.7 and FlashAttention candidates for sources, hashes and verification limits.
Install external runtime assets
Optional character RAG is off by default and works with remote and local Main Chat. It includes a buildable Chinese/Japanese starter corpus and supports personal knowledge directories. Settings shows applied thresholds and loading state. RAG adds local embedding/Torch dependencies; the guide covers setup, diagnostics and evaluation limits.
The default local-voice profile uses the Qwen ASR and GPT-SoVITS v3 voice packs. The visual and character packs are optional:
uv run --locked --no-sync python tools\external_assets.py verify C:\Downloads\amadeus-asr-qwen3-0.6b.zip
uv run --locked --no-sync python tools\external_assets.py install C:\Downloads\amadeus-asr-qwen3-0.6b.zip
uv run --locked --no-sync python tools\external_assets.py verify C:\Downloads\amadeus-voice-kurisu-gpt-sovits-v3.zip
uv run --locked --no-sync python tools\external_assets.py install C:\Downloads\amadeus-voice-kurisu-gpt-sovits-v3.zip
Optional scene and KTX2 character animation
uv run --locked --no-sync python tools\external_assets.py install C:\Downloads\amadeus-visual-runtime.zip
uv run --locked --no-sync python tools\external_assets.py install C:\Downloads\amadeus-character-kurisu.zip
uv run --locked --no-sync python tools\external_assets.py status
To try Kurisu v2Pro, install the separately supplied experimental add-on after the v3 voice pack. It contains the v2Pro GPT/SoVITS checkpoint pair and ERes2Net speaker encoder, and reuses the BERT, CNHuBERT, and reference audio already installed by the v3 pack:
uv run --locked --no-sync python tools\external_assets.py verify C:\Downloads\amadeus-voice-kurisu-gpt-sovits-v2pro-experimental.zip
uv run --locked --no-sync python tools\external_assets.py install C:\Downloads\amadeus-voice-kurisu-gpt-sovits-v2pro-experimental.zip
In Settings → Voice → Voice backends → Embedded GPT-SoVITS model, select
Kurisu v2Pro · experimental under Voice checkpoint profile, then restart
the backend. For .env configuration, set TTS_VOICE_PROFILE=kurisu_v2pro;
kurisu_v3 remains the default in .env.example. Named profiles select both
checkpoints together. The embedded runtime supports v1, v2, v2Pro, v2ProPlus,
and v3 checkpoints; use custom with TTS_GPT_MODEL_PATH and
TTS_SOVITS_MODEL_PATH for another compatible pair. v2Pro/v2ProPlus also require
the speaker-encoder weight supplied in the add-on. Selecting v2Pro does not
enable the optional TTS_T2S_FLASH_ATTN path; it remains off by default.
v2ProPlus is also supported by the same inference pipeline, including
speaker conditioning, session caching, CUDA Graph, and streaming playback.
To use it, select Custom checkpoint pair (TTS_VOICE_PROFILE=custom) and
set the GPT and SoVITS paths to a compatible v2ProPlus pair, then restart the
backend. It uses the same ERes2Net speaker encoder as v2Pro. There is currently
no named Kurisu v2ProPlus profile or separate Plus asset pack; the experimental
Kurisu pack above contains v2Pro weights. The real-inference validation for this
change used v2Pro; v2ProPlus was not separately exercised with real weights.
If a prepared Qwen pack is unavailable, download the upstream snapshot into the same canonical location. Runtime inference remains offline and will not start an implicit download when the microphone is opened:
uv run --locked --no-sync python -c "from huggingface_hub import snapshot_download; snapshot_download('Qwen/Qwen3-ASR-0.6B', local_dir='assets/models/asr/qwen3-asr-0.6b')"The Japanese GPT-SoVITS frontend prepares an OpenJTalk dictionary on first use. Prewarm it once if the normal application launch must remain offline:
uv run --locked --no-sync python -c "import pyopenjtalk; print(pyopenjtalk.g2p('準備完了'))"Configure and launch
Copy .env.example to .env (Copy-Item .env.example .env on Windows;
cp .env.example .env on macOS), provide the DeepSeek API key, then review Settings:
- Models:
deepseek, the official endpoint,deepseek-v4-flash, and an API key; - Voice: Fish Audio S2.1 + Kurisu is the recommended remote TTS profile; MiMo and OpenAI-compatible endpoints are also supported. The L4 local stack also needs a Qwen model directory, a compatible GPT-SoVITS checkpoint pair (Kurisu v3 by default or experimental Kurisu v2Pro), reference audio/text, microphone, AEC, and barge-in;
- General: optional character-pack status and presentation settings.
- Windows:
run_electron_utf8.bat, the shared launcher for L1–L4; it discovers.venvautomatically. - macOS:
cd electron && npm run electron:dev.
Amadeus Wallpaper.app.
Build, verification, and LaunchAgent installation steps are documented in
macOS wallpaper startup.
Use Restart backend to apply after changing startup settings. A Not installed character pack is healthy and does not disable Chat, Work, or headless startup.
The default B2 AppSession action path does not block first-time setup. Chat and Settings still start without supported AUIP action-model credentials; application actions remain blocked, and Settings displays the missing capability.
VN Player setup (Windows, experimental)
VN Player needs a separately installed text extractor and a compatible game. Choose either 0xDC00 Agent or LunaTranslator and follow its setup below.
0xDC00 Agent
For this route, the hook script is the game's extraction .js file;
Full script for alignment is a separate, optional story-text file and can be
left empty. Amadeus does not install Agent, game scripts, or games for you.
- Download the Windows build from 0xDC00 Agent releases
agent.exe and its data folder together.
- In Agent's script selector, use update scripts to obtain the
data/scripts. The installation guide
also explains manual installation and how to check the script first.
- Enable Agent's WebSocket output at
127.0.0.1:9001, the desktop profile's
- Open VN Player → Add game. Choose a game type, select 0xDC00 Agent, then
.exe, its hook .js, and agent.exe. Choose
Steam if the game needs Steam startup, or I will start the game for
another launcher. Leave the full story script empty to begin with live text.
- Click Save and test text, advance several dialogue lines, and compare the
LunaTranslator
Use the full LunaTranslator application for this route. **Agent and its .js
scripts are not required**; standalone LunaHook does not provide this integration's
original-text network service by itself.
LunaTranslator.exe.
- Start the game. In Luna's HOOK mode, select its process, advance dialogue,
- Enable Luna's network service
- In VN Player → Add game, select Luna original text (experimental). Set
ws://127.0.0.1:/api/ws/text/origin , replacing
/api/ws/text/trans or a web-page address.
- Choose I will start the game to manage startup externally; the game executable
.exe for automatic exe/Steam startup
or game-window vision. Full script for alignment remains optional.
- Use Save and test text, advance dialogue, and compare the preview before
Amadeus does not launch Luna or select its hooks. End session disconnects the stream without closing Luna. See the Luna integration details.
For either source's missing text, script dependencies, and connection failures, see troubleshooting.
Compatibility routes
Optional local LLM
To use llama.cpp instead of the remote Main Chat baseline, set
LLM_PROVIDER=local, configure its executable/GGUF or an existing
OpenAI-compatible endpoint, and start it when needed:
.\start_llm_server.batLM Studio, Ollama, llama-cli, and hybrid profiles remain available, but none is an automatic fallback after a DeepSeek failure.
Optional remote model recommendations
These are recommended profiles for the current APIs. They do not change the role split above, and Amadeus never switches Providers silently after an endpoint failure:
| Responsibility | Recommended profile | Current boundary |
|---|---|---|
| Main Chat API | DeepSeek-V4-Flash-0731: DEEPSEEK_BASE_URL=https://api.deepseek.com and DEEPSEEK_MODEL_NAME=deepseek-v4-flash | deepseek-v4-flash is the stable API alias currently pointing to the 0731 release; the dated version is not used as the runtime model id. |
| Remote speech synthesis | Fish Audio S2.1: TTS_BACKEND=fish_audio, FISH_TTS_MODEL=s2.1-pro-free; Kurisu voice: FISH_TTS_REFERENCE_ID=b450b19370434173b121446057622e9b | Bidirectional WebSocket streaming; locally committed sentence chunks use text → flush, with incremental audio output. Existing Chat sentence scheduling is preserved. |
| Multimodal / Vision | Prefer gemini-3.7-flash; use gemini-3.5-flash as a more conservative compatibility profile | Host-owned visual context performs capture in-process, while image delivery still follows the Main Chat Provider. Independent Gemini Vision API routing is not implemented and does not imply restoring the retired Gemini Live sidecar. |
| Work execution Provider | Pi for daily tasks; Codex App Server for complex coding | Desktop installation includes the pinned Pi runtime; configure model credentials. OpenClaw remains optional for explicit selection; Browser retains managed-page operations. |
| Work execution model | Codex App Server may explicitly select a GPT-5.6-family model or deepseek-v4-flash | The execution model belongs to the Work Provider and does not share Main Chat routing or credentials. |
| AUIP runtime action decisions | AUIP_ACTION_PROVIDER=openai, AUIP_ACTION_MODEL=gpt-5.6-terra, AUIP_ACTION_REASONING_EFFORT=low, and AUIP_ACTION_SERVICE_TIER=fast | This model decides AppSession actions and participation; it is not the execution Provider that authors an AUIP Artifact. fast requires availability for the API project. |
Recommended remote TTS: Fish Audio + Kurisu
After installing L2 voice, select Fish Audio under **Settings → Voice → Speech synthesis**, enter the API key, and restart the backend. Use:
| Setting | Recommended value |
|---|---|
| Fish inference model ID (S2.1 free model) | s2.1-pro-free |
| Kurisu voice / reference ID | b450b19370434173b121446057622e9b |
| Voice page | Makise kurisu / 牧濑红莉栖 |
| WebSocket endpoint | wss://api.fish.audio/v1/tts/live |
| Latency mode | balanced |
The equivalent local .env configuration is:
TTS_BACKEND=fish_audio
FISH_TTS_API_KEY=<your-fish-api-key>
FISH_TTS_MODEL=s2.1-pro-free
FISH_TTS_REFERENCE_ID=b450b19370434173b121446057622e9b
FISH_TTS_LATENCY=balanced
The Japanese voice ID is separate from the inference model ID. GUI credentials
use the existing encrypted store. This remote recommendation does not change the
default embedded GPT-SoVITS backend. A three-trial Windows baseline with DeepSeek
measured a 3.70 s median from chat.send to the first non-silent device write,
plus roughly 91 ms reported output latency; other networks and cold starts vary.
See Fish Audio setup, chunk probes, and audio checks.
External models and runtime assets
Model weights, reference audio, character packs, and large or copyright- sensitive media are distributed separately. The source repository keeps the required icons, default wallpaper, schemas, validators, and installation tool.
Visit the Code Amadeus resource hub for available resource links and download information.
The local-voice directory contracts are asr-qwen3-0.6b and
voice-kurisu-gpt-sovits-v3, with the optional
voice-kurisu-gpt-sovits-v2pro-experimental add-on for v2Pro. The v3 pack provides
shared resources required by the add-on. visual-runtime and character-kurisu
affect scene and character presentation. See the asset bundle guide
for pack contents and installation details.
uv run --locked --no-sync python tools\external_assets.py verify C:\path\to\asset-bundle.zip
uv run --locked --no-sync python tools\external_assets.py install C:\path\to\asset-bundle.zip
uv run --locked --no-sync python tools\external_assets.py status
A bundle can be installed from any tier: external_assets.py uses only the
Python standard library. Running local voice models additionally requires the
matching model dependencies and hardware; installing a bundle alone does not
add them. See installation profiles for the qualified
cu124 profile and the ROCm experimental boundary.
A SpriteForge character package ultimately lands at:
assets/spriteforge/runtime/kurisu/
  runtime_manifest.json
  graph_config.json
  spriteforge_mouth_config.json
  textures/
The installer preserves the canonical assets/... layout, verifies SHA-256,
skips identical files, and rejects unexpected overwrites. See
external asset bundles and the
character-pack contract.
Wallpaper mode (Lively Wallpaper recommended)
On Windows, the open-source
Lively Wallpaper is the recommended
host for Amadeus's web wallpaper. Windows now starts in managed wallpaper mode:
it prepares Lively 2.2.1.0, mounts the scene, and restores the previous wallpaper
when Quit Amadeus is selected in the Amadeus tray menu. --no-wallpaper
opens an ordinary window. Missing Lively is installed through winget; source
builds need .NET 8 SDK for the helper's first build. See the
Windows lifecycle and experiments.
Wallpaper Engine remains compatible. Set AMADEUS_WALLPAPER_HOST=external for
the original manual workflow: start Amadeus, add the URL below to Lively
(WebView2 recommended), then click Wallpaper in the Amadeus sidebar:
http://127.0.0.1:17777/wallpaper/lively/index.htmlThis stable entry discovers the actual asset and bridge ports automatically
and waits in place while wallpaper mode is off. Do not hard-code 17778 or
17797. For diagnostics, run
uv run --locked --no-sync python tools\run_wallpaper_engine_bridge.py and use the printed Lively URL.
See the Lively entry guide.
macOS has no corresponding Lively/Wallpaper Engine desktop host. When Wallpaper is activated, Electron hosts the full scene at the desktop level and uses a separate transparent window for the interactive Canvas. The scene remains click-through so it does not block Finder desktop icons. The macOS Electron wallpaper host has community real-device verification; dependency and CI work is tracked by #46, and signing, notarization, and an installer are not included yet.
Graphics performance
All PixiJS character and wallpaper surfaces share one graphics profile. Configure
it in Settings → Graphics & performance, or through .env:
GUI preview (custom settings awaiting restart).
| GRAPHICS_PROFILE | Maximum frame rate | Resolution | Purpose |
|---|---:|---:|---|
| standard (default) | 60 FPS | Native device-pixel ratio | Preserve animation quality |
| power_saving | 30 FPS | Up to 1.5× | Reduce GPU use, power consumption, and heat |
| custom | RENDER_MAX_FPS | RENDER_MAX_RESOLUTION | Set a custom performance budget |
Custom frame rates support 10–240 FPS and resolution supports 0.25–4.0. Example:
GRAPHICS_PROFILE=custom
RENDER_MAX_FPS=45
RENDER_MAX_RESOLUTION=1.25
When Wallpaper Engine supplies a user FPS setting through
applyGeneralProperties().fps,
the runtime uses the lower of that setting and the project profile. Electron,
Lively, and other character surfaces use the project profile directly.
The GUI exposes custom FPS and pixel-density limits when Custom is selected,
preserving those values when switching presets. Saved desktop settings apply on
backend restart; reopen existing character and wallpaper windows afterward.
The page shows current backend limits separately from saved choices. Wallpaper
Engine may impose a lower FPS cap; displayed limits are not measured frame rates.
Experimental texture sampling (off by default)
RENDER_TEXTURE_SAMPLING=false preserves the existing full-frame loading and
playback rules. On 16GB systems or other memory-constrained setups, consider
trying Experimental texture sampling in the graphics page with the 30 FPS
power-saving profile. The toggle is independent of presets and remains off by
default. The equivalent .env values are:
GRAPHICS_PROFILE=power_saving
RENDER_TEXTURE_SAMPLING=true
When enabled, character frames are sampled against the effective FPS budget, preserving required hold frames, animation duration and mouth-anchor indices. One local 30 FPS offscreen experiment reduced CPU texture buffers by about 50% with similar frame pacing. This is not a claim of halving total RAM or VRAM; 16GB hardware and long-running sessions still need validation. See the experiment and limitations.
Restart Amadeus/the backend and reopen the wallpaper after changing this option.
Changing the draw FPS alone does not rebuild the texture cache. To restore the
existing behavior, set RENDER_TEXTURE_SAMPLING=false and restart in the same way.
Configuration ownership
Startup values use one precedence order:
- Parent-process environment variables (highest authority; shown as locked in the GUI)
- Electron desktop settings
- Repository-root
.env - Defaults in
config/settings.py
.env. Ordinary models, voice, microphones,
Providers/MCP, vision, avatars, and character-pack status belong in the GUI;
advanced diagnostics, experimental thresholds, and test-only flags remain in
.env. Secrets use the operating system's safeStorage encryption. See
configuration ownership and
local instance authentication.
Current release boundaries
| Scope | Status |
|---|---|
| L1/L2 (text + remote voice) | Source deployment on Windows, macOS, and Linux; Windows is the reference platform, with separate macOS L1/L2 and Linux CI |
| Linux | Source deployment verified on real hardware; Ubuntu 24.04 CI covers L1, L2 Voice source builds and the Electron build. See Linux setup for environment-specific notes |
| L3 CPU VAD | No NVIDIA GPU required; uses an explicit CPU build selection |
| L4 cu124 (local CUDA 12.4 voice) | Windows + NVIDIA; follows the qualified local-model configuration |
| AMD ROCm 7.2.1 | Targets GPUs in AMD's official Windows support matrix; local-rocm experimental profile with Qwen ASR / GPT-SoVITS sidecars. See setup and validation |
| NVIDIA cu128 | Experimental Torch 2.7.0 lock and installation CI; full device/model qualification pending |
| Apple Silicon MPS | Supported through local-mps; verified on real hardware |
| 8 GiB VRAM / 16–32 GiB RAM | Target configuration; actual use depends on model selection |
| Remote DeepSeek Main Chat | First-release default profile |
| Remote ASR / TTS | Explicit compatibility path, never a silent fallback |
| Electron installer | Not provided yet; launch from source |
| macOS Electron wallpaper host | Community real-device verification; dependency/CI tracked by #46, with no signing, notarization, or installer yet |
| Docker | Not a supported desktop installation path |
| SpriteForge character pack | Externally distributed; source starts without it |
| VTS | Disabled-by-default compatibility route |
| VN Player | Experimental; installation and first text capture |
| Wallpaper hosts | Lively / Wallpaper Engine on Windows; the macOS Electron host has community real-device verification as noted above |
| PyQt / old wallpaper hosts | Retired from public mainline |
| Claude CLI Provider | Committed future mainline Provider; no live caller yet |
Development and contribution
uv sync --locked --extra dev      # Core + dev tools; removes unselected voice/model tiers
To retain voice/models, append --extra dev to the complete installation command
uv run --locked --no-sync python tools\verify_python_environment.py --profile ci
uv run --locked --no-sync python -X utf8 tools\run_tests.py
cd electron
npm ci
npm run build
npm audit --audit-level=high
Read CONTRIBUTING.md and ROADMAP.md before submitting a change. Product semantics, authority, protocols, Providers/MCP/Skills, Projects/Drafts/Artifacts, or AUIP changes should start with an Issue. Small fixes, documentation, tests, and presentation-only UI changes may open a PR directly. Report security issues privately under SECURITY.md.
Public history and license
The public repository begins with one prepared root commit. Internal development commits, experimental branches, deleted character media, models, credentials, sessions, personal paths, and original co-author metadata were not migrated. The source itself remains included according to the reviewed release boundary.
Amadeus first-party source and modifications are open-source under the GNU Affero General Public License v3.0 (AGPL-3.0). Third-party components retain their own licenses, recorded under LICENSES and THIRD_PARTY_NOTICES.md. The code license grants no automatic rights to character, model, reference-audio, or external asset packs.
Related projects
- Aqua-TTS: an MIT-licensed low-latency GPT-SoVITS v3 inference runtime. Amadeus does not require Aqua to start today.
- Amadeus SpriteForge: public 0.1.0 Source Alpha for local sprite inspection, behavior-graph editing, and KTX2 character-pack preview/export. Licensed under AGPL-3.0-only; generation services are separate from the Amadeus runtime.
- AUIP: the experimental application-session / typed-action protocol implemented in Amadeus. The separate repository documents its status and public implementation entry points; a separately versioned SDK and conformance suite are not yet published.
- GPT-SoVITS: the embedded speech-synthesis inference foundation.
- OpenClaw: an optional external Work gateway.
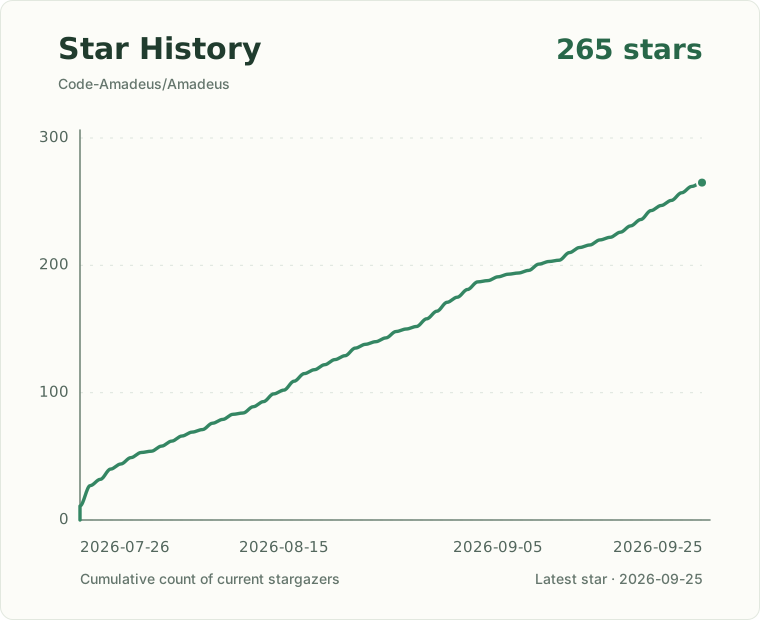
Star History